
DeepSeek V4.1 Flash
Multimodal chat and agents
Mac: macOS 15 or later on Apple silicon, and it updates itself. iPhone: through TestFlight, iPhone 15 Pro or later on iOS 18.
- Download Minirun
- Models > Find Models — pick DeepSeek V4.1 Flash
- Verify all files
- New chat
About
DeepSeek V4.1 Flash — a 552B multimodal mixture-of-experts model with a million-token context. It holds a conversation on a Mac and on an iPhone 16 Pro, streaming the 517 GB container straight off your drive.
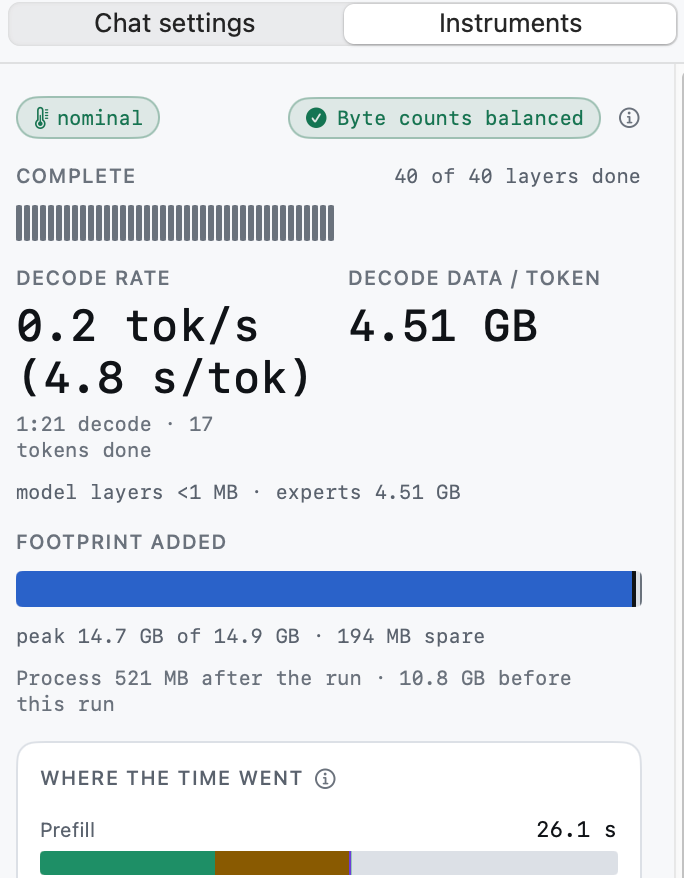
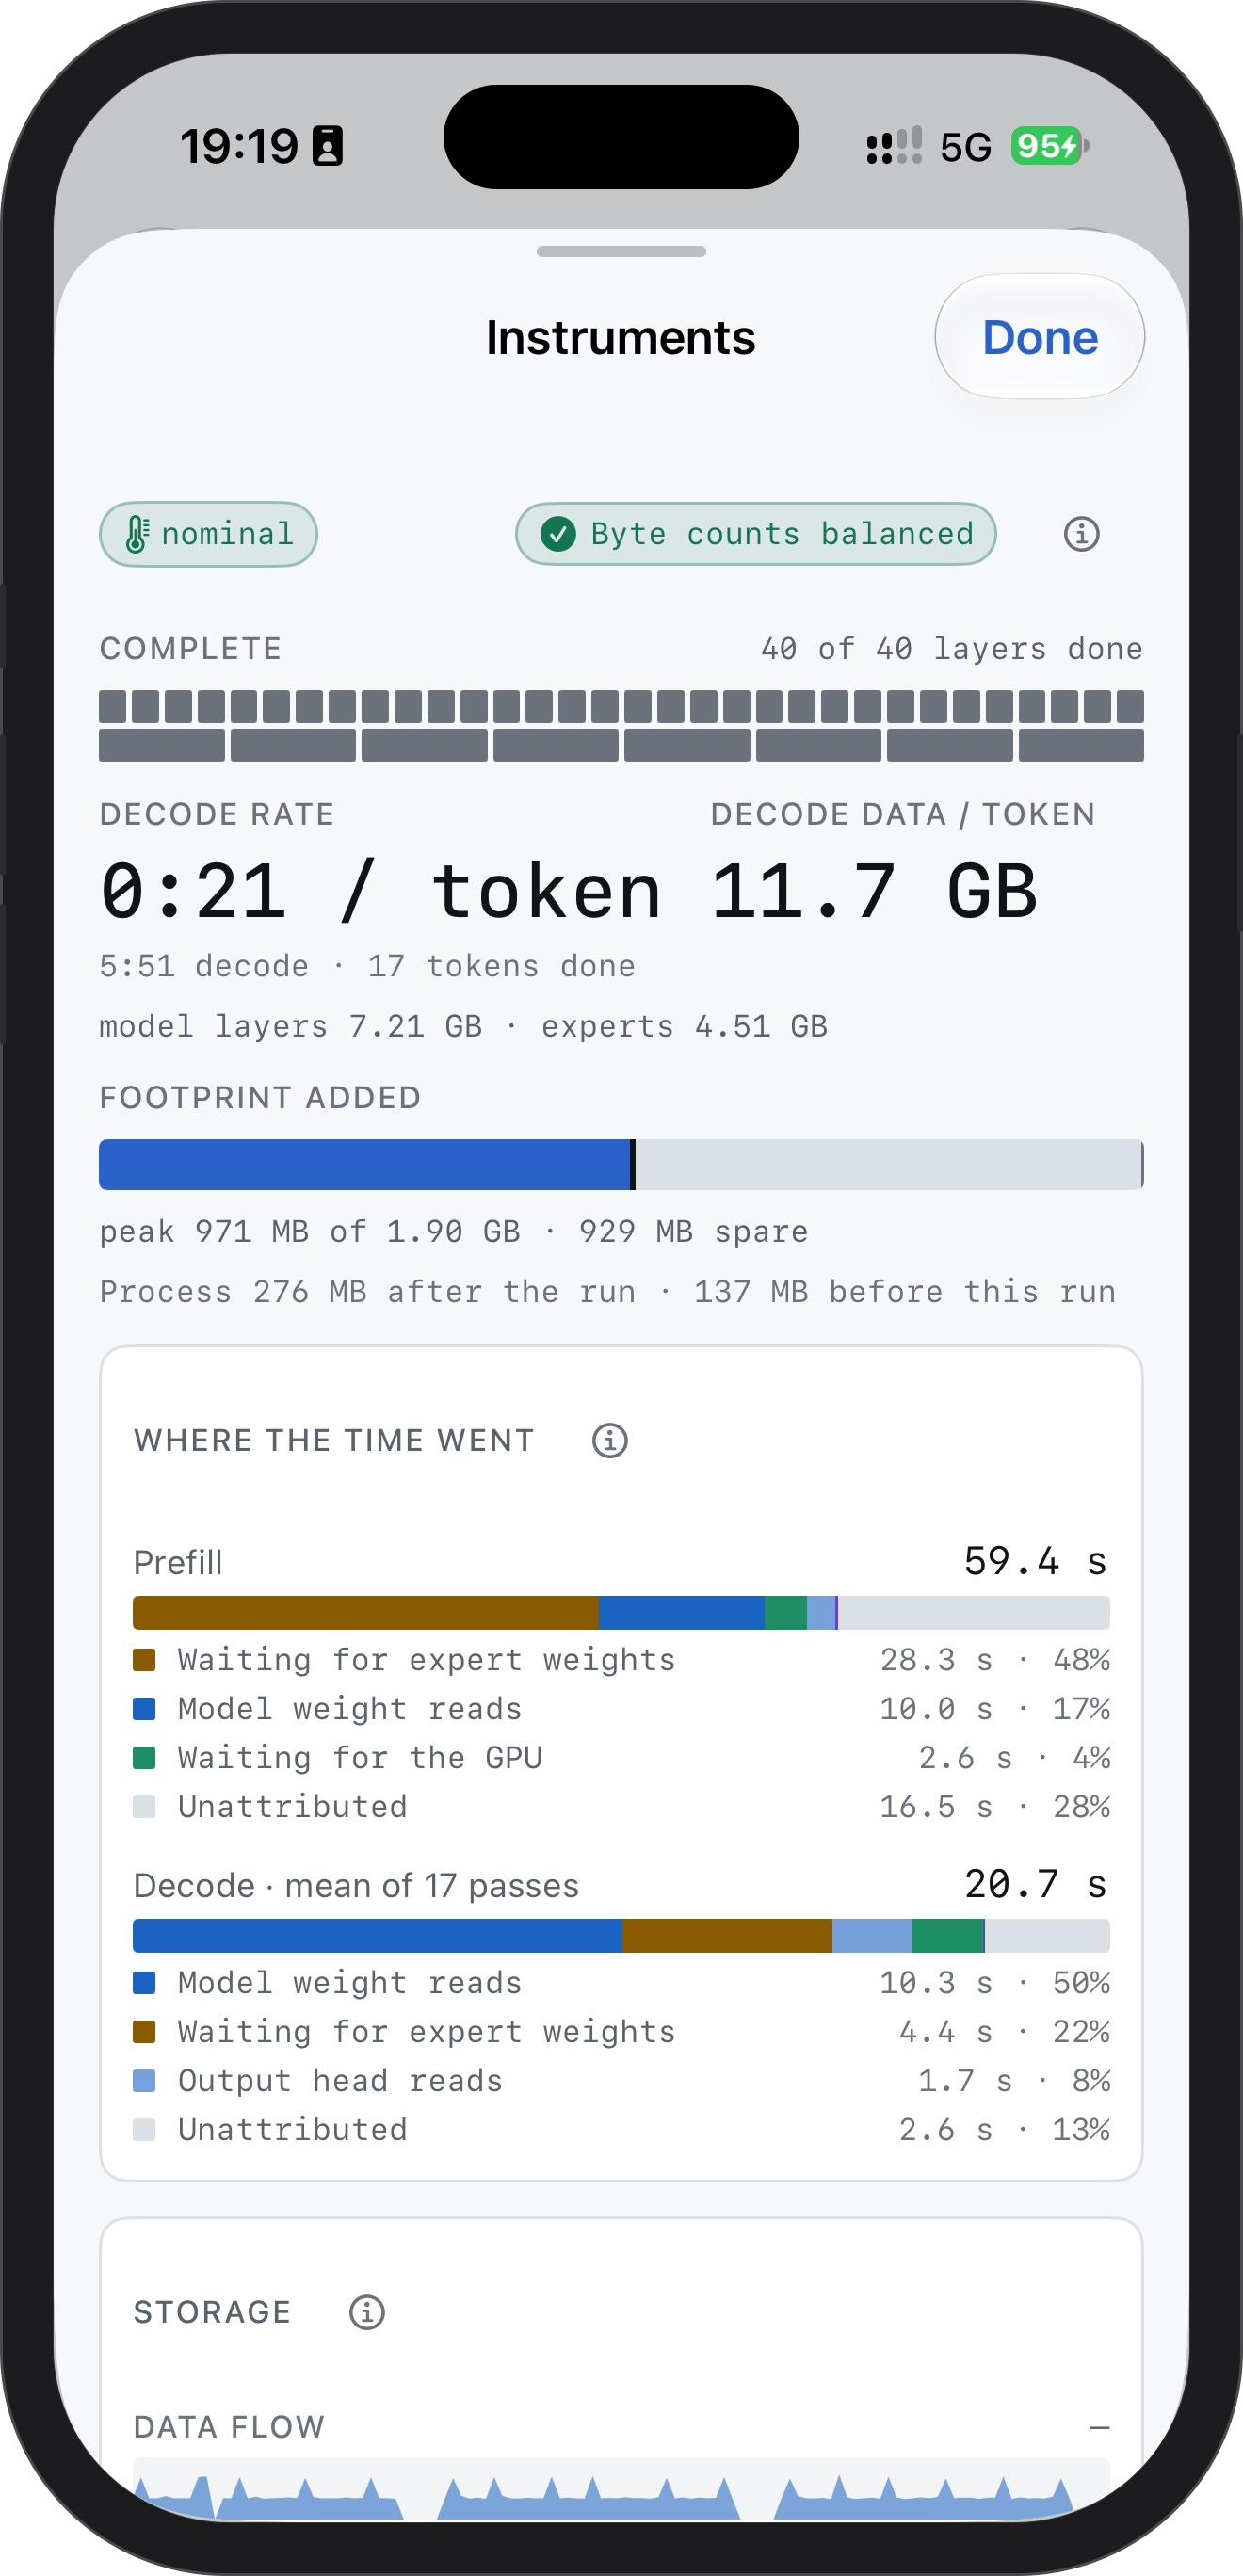
On a Mac it answers at about 5 s / token at the 14.9 GB Balanced budget, where it keeps all forty of its layers and its output head in memory and reads 4.5 GB of experts a token. It runs at 3.4 GB, streaming everything. On an iPhone 16 Pro: about 21 s / token at 1.9 GB, reading 11.7 GB a token. The first reply takes about half a minute to start on the Mac and about a minute on the phone. The pace depends on the drive, the cable and the budget.
What you need
About 3.4 GB of memory on Mac, 1.9 GB on iPhone 16 Pro, and 517 GB free on your SSD.
Model requirementsTechnical details
- Stored precision
- FP4 experts · FP8 matrices and memory tables · BF16/F32 remainder
- Container size
- 517 GB
- License
- MIT
- Repository
- nanguoyu/DeepSeek-V4.1-Flash-minirun
- Source model
- deepseek-ai/DeepSeek-V4.1-Flash